About Us
The argument in favor of using filler text goes something like this: If you use real content in the Consulting Process, anytime you reach a review point you’ll end up reviewing and negotiating the content itself and not the design.
AI Competitor Research for Startups: The Report I Build for Indian Founders Before They Pitch
AI Competitor Research for Startups: The Report I Build for Indian Founders Before They Pitch
AI Competitor Research for Startups: The Report I Build for Indian Founders Before They Pitch
Almost every early pitch deck I review has a competition slide with four logos and a tick-mark table where the founder’s company wins every column. Investors have seen that slide thousands of times. It rarely survives the first follow-up question. That is why I built a workflow for AI competitor research for startups that does the digging before the pitch, not after it.
I designed it with my team for Indian founders who are preparing to raise money or step into a new market. You enter your company’s website. The workflow finds similar companies with Exa AI, collects public data about each one from sources like Crunchbase, Wellfound and review sites using Firecrawl scraping and SerpAPI, asks GPT-4o to pull out clean facts, and writes everything into a Notion report you can edit. This article covers how it finds rivals, all six nodes, why the order matters, what fails, setup, how to turn it into a market map, and how my team runs it for clients.
The competitor slide investors question most
“You have no competitors? Then either there is no market, or you have not looked.”
Some version of that line is said in pitch meetings all the time. Early-stage investors in India and abroad do not expect you to have zero competition. They expect you to know who else is chasing the same customer, how those players make money, and why your angle still wins. A weak slide tells them you have not done that homework.
The trouble is that real homework takes days. You search Google, open twenty tabs, copy funding numbers from one site and pricing from another, read app reviews to understand what customers hate, and paste it all into a slide. Most founders do this once, in a hurry, the night before a meeting. Then the market moves and the slide goes stale.
There is another quiet problem with manual research: bias. Founders naturally look hardest at the competitors they already fear and skip the ones that seem unrelated. Investors, who see many decks in the same sector, often know the names you missed. Walking into a meeting and hearing “What about this company?” for the first time is a bad feeling, and a preventable one.
A good competitor view is really a market map: who plays where, at what price, for which customer. Building that map from scratch is exactly the kind of repetitive research that software can do well, as long as a human checks the output before it goes in front of an investor.
This is where AI competitor research for startups earns its place. It does not replace your understanding of the market. It gives you a fuller, fresher starting point in an hour instead of three days, so the time you do spend goes into thinking about what the data means for your pitch.
How AI competitor research for startups finds rivals you missed
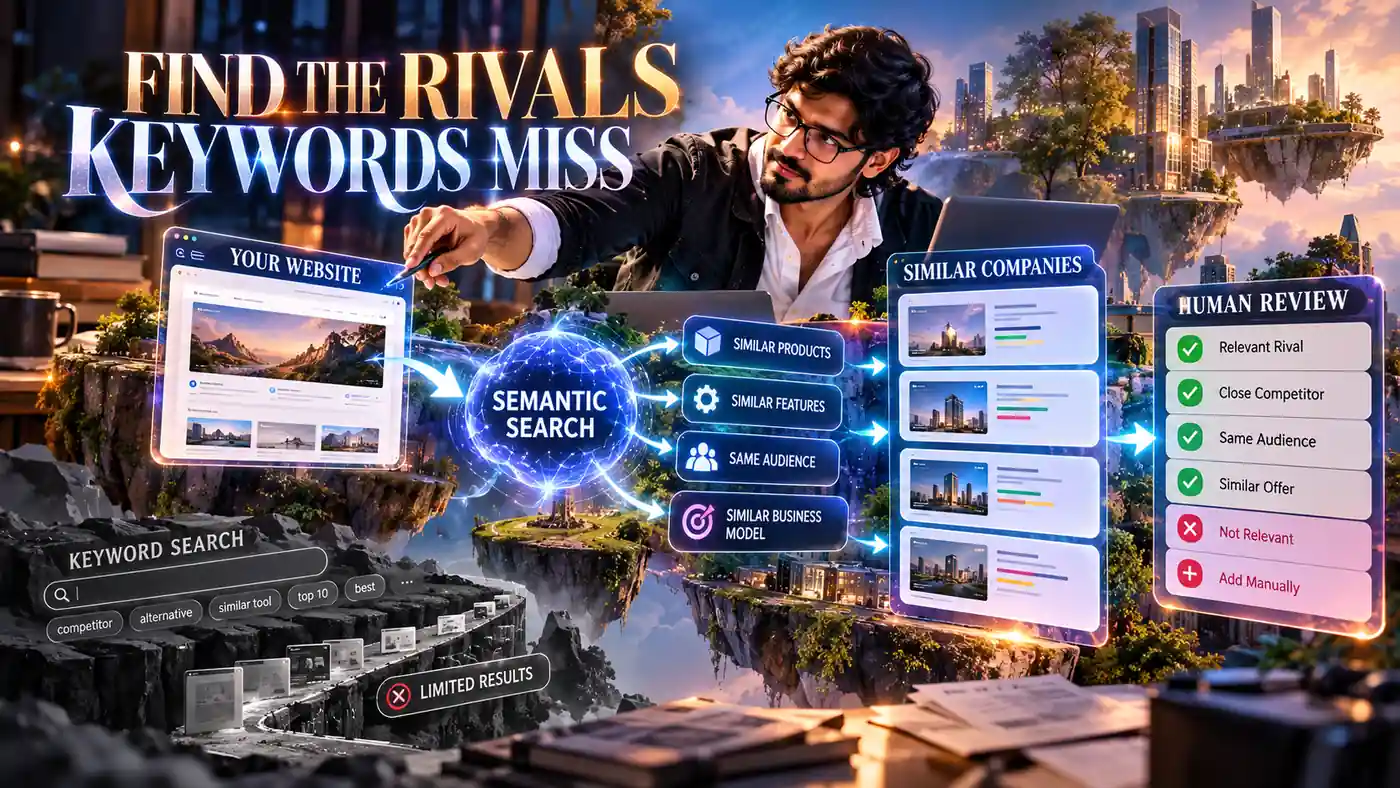
Keyword search only finds companies that describe themselves with the same words you use. If you call your product “vernacular upskilling for blue-collar workers” and a rival says “job-ready courses in regional languages”, Google may never put you side by side. Exa AI works differently. Its search is built around meaning, and it has an option to find pages similar to a given URL. You give it your homepage, and it returns companies whose websites talk about the same kind of thing.
That is the first step of AI competitor research for startups in this workflow. The full flow looks like this:
Your website URL
      |
      v
Exa AI: find similar companies
      |
      v
For each rival (one at a time)
      |--> Firecrawl: scrape public profile pages
      |--> SerpAPI: search results, reviews, news
      v
GPT-4o: extract company, product and review facts
      |
      v
Aggregate: one dataset of all rivals
      |
      v
Notion: competitor report page
The rivals Exa returns are a starting list, not a final answer. I always review it and remove irrelevant names, and I often add two or three companies the founder already knows about. Sometimes the most useful result is a foreign company doing the same thing, which tells you what an Indian version might grow into.
Why does this matter so much in India? Many Indian startups compete not only with other startups but with offline habits, family businesses and large conglomerates entering new categories. A keyword search will not surface most of those. Starting from meaning rather than exact words, and then adding the rivals you already know, gives a far more honest list. That honesty is the whole point of AI competitor research for startups: showing investors you see the full field, not just the players that make you look good.
All six nodes and why each exists
Here is every node in the competitor analysis automation, in order, with what happens if it breaks.
| # | Node | Why it exists | Hands over to | If it breaks |
|---|---|---|---|---|
| 1 | Form or Manual Trigger | Takes your company URL and, optionally, a few known rivals | Exa request | Nothing starts |
| 2 | HTTP Request: Exa AI | Finds companies with similar websites | Loop Over Items | Rival list comes back empty |
| 3 | Firecrawl and SerpAPI (HTTP Requests) | Collect public pages, search results and review snippets for each rival | OpenAI | There is nothing to analyse |
| 4 | OpenAI GPT-4o with structured output | Turns messy page text into fixed fields: founded, funding, pricing, customers, complaints | Aggregate | Output is loose text you cannot compare |
| 5 | Aggregate | Combines every rival into one list | Notion | Report shows only one rival |
| 6 | Notion: create page | Writes the report into your workspace | End | Everything runs but no report appears |
Node 4 is where the real value is created. By forcing GPT-4o to fill a strict schema, every competitor ends up with the same set of fields. That makes the Notion report comparable row by row, instead of six different essays.
A typical schema I use has about twelve fields: company name, website, year founded, headquarters, funding stage, total funding, main product, pricing model, starting price, target customer, top three customer complaints, and source links. You can add or remove fields, but keep the list short enough that the model fills it reliably. Long schemas tend to come back with more empty or confused fields.
Firecrawl scraping and SerpAPI within site terms
Note: Firecrawl scraping reads public web pages and returns clean text. SerpAPI returns search engine results through an API. I only collect publicly visible information and I respect each site’s terms. LinkedIn does not allow scraping, so I rely on search result snippets there instead of logged-in pages. For heavy Crunchbase use, its paid API is the proper route.
Why extraction waits until scraping is done
It might seem faster to ask GPT-4o directly, “Tell me about my competitors.” That is exactly what I avoid. A language model answering from memory will happily produce funding numbers and founding years that sound right but are out of date or simply wrong. In a pitch, one wrong number can cost you credibility with an investor who knows the space.
So the order is fixed: discovery first, then collection, then extraction. The model never invents data. It only reads text that Firecrawl scraping and SerpAPI actually collected and puts it into fields. If a field is not in the collected text, the instruction is to leave it empty and mark it “not found”. An empty cell is far better than a confident guess.
The Loop Over Items node plays a part here too. Each rival is scraped and extracted separately, so one slow or blocked site does not stall the entire run. If a website refuses Firecrawl scraping, that rival simply gets fewer fields filled, and the loop moves on to the next one. At the end, Aggregate collects whatever each pass produced.
This order also makes the report checkable. For each competitor, the workflow keeps the source links it used. When you or an investor want to verify a number, the link is right there in the Notion report.
When scraping fails or data looks wrong
Research workflows touch many outside websites, so some failures are normal. These are the common ones and their fixes.
| Symptom | Cause | Fix |
|---|---|---|
| Exa returns unrelated companies | Your homepage is vague or mostly images | Use a product page with clear text, or add a short description |
| Firecrawl returns an empty page | The site blocks bots or loads everything with JavaScript | Skip that source and rely on SerpAPI snippets for that rival |
| SerpAPI error 401 | Wrong or expired API key | Update the key in credentials |
| SerpAPI results look foreign-only | Search location not set | Set the location to India and the Google domain to google.co.in |
| Funding amounts differ between sources | Old or conflicting reports | Show both with dates and source links; let a human decide |
| Indian company details look off | Profile sites are outdated | Check the registered name and status on the MCA portal |
| Notion shows an error | Page too long or integration not shared with the database | Split long text into smaller blocks and share the database with the integration |
The MCA check deserves a mention. For Indian startups, the Ministry of Corporate Affairs records are the most reliable source for the legal company name, incorporation date and status. I treat them as the final word over any profile site.
One more habit worth building: date everything. Funding rounds, pricing and team sizes change often. When AI competitor research for startups shows a number, the Notion report also shows when that number was published, so no one mistakes a 2022 figure for today’s reality.
Setup, step by step
- Create accounts and API keys for Exa AI, Firecrawl, SerpAPI and OpenAI. Each offers a free tier or trial credits; check current limits on their sites.
- In Notion, create a database called “Competitor Research” with properties such as Company, Website, Founded, Funding, Pricing, Target customer, Top complaints and Sources.
- Create a Notion integration, copy its secret and share the database with it.
- In n8n, add credentials for all five services. Keep every key inside the workflow platform, never in the Notion page.
- Add a Form Trigger with fields for your website URL and up to three known competitors.
- Add an HTTP Request node that calls Exa’s find-similar endpoint with your URL and a result limit of around ten.
- Add Loop Over Items, then inside the loop the Firecrawl and SerpAPI requests for each rival.
- Add the OpenAI node with a JSON schema for the fields you want, and the instruction to use only the collected text.
- After the loop, add Aggregate, then the Notion node that creates one page per run with a summary and a row per competitor.
- Run it on your own company first, check every row by hand, then adjust the schema until the Notion report reads the way you need.
The first run teaches you the most. You will notice which sources are useful in your sector and which only add noise, and you can drop the noisy ones from the loop.
A small tip on the Notion side: keep one database for all runs and add a “Run date” property. That way, your Notion report becomes a history. Six months later you can filter by date and see which competitors raised money, changed pricing or quietly disappeared, which is often the most interesting story for your next investor update.
Costs stay modest for a typical run of ten competitors, because each API call is small. The biggest cost driver is usually the number of pages you scrape per rival. Start with two or three pages each, such as the homepage, pricing page and one review source, and add more only if the report feels thin.
Turning the Notion report into a market map
A Notion report full of facts is useful. A market map is what investors remember. Once the data is in Notion, I pick two axes that matter to your customer and place each company in a 2×2 grid.
| Low price | High price | |
|---|---|---|
| Broad audience | Mass-market players competing on volume | Established brands with wide range |
| Niche audience | Specialists serving a small segment cheaply | Premium specialists with deep features |
Axis ideas that work well for Indian startups:
- Price point vs breadth of offering
- Tier-1 cities vs Bharat (tier-2, tier-3 and rural users)
- English-first vs vernacular-first
- Self-serve app vs assisted or offline sales
- Consumer (B2C) vs business buyers (B2B)
The gap in the grid is your pitch. If every rival sits in “tier-1, English-first”, and you are building for vernacular users in smaller towns, the market map makes that visible in one glance. The Notion report underneath gives you the facts to defend it.
I usually draw the final market map as a simple slide from the Notion data. The report stays the working document you update; the slide is the snapshot you show. When you rerun the workflow before the next funding round, the map can be refreshed in minutes rather than rebuilt from nothing.
How my team runs competitor analysis automation for clients
When a founder hands this job to my team, my team follows a simple checklist. Timelines depend on the number of competitors and how much manual checking your sector needs.
The research workflow shown here is a sample. For a client, my team designs it on the platform of their choice, or reshapes the workflow they already run.
- Understand your product, customer and the market you are entering
- Run discovery and agree on the final rival list with you
- Collect and extract data, then check every key number against its source
- Verify Indian competitors on the MCA portal
- Deliver the Notion report and a draft market map
- Walk you through it so you can answer investor questions confidently
- Hand over the workflow so you can rerun the competitor analysis automation before your next round
The handover matters. Markets shift every few months, and a competitor report is only useful while it is fresh. With the workflow in your own n8n, a founder can run AI competitor research for startups again before every board meeting or new market launch, without paying for the same research twice.
My team also writes a one-page summary on top of the Notion report: the three competitors that matter most, where each is strong, and where your startup has a clear opening. Founders tell investors a far sharper story with that page in hand.
Custom versions for D2C brands, SaaS and local service businesses
The sources that matter change by sector. I adjust what Exa AI searches for and which pages the loop visits.
| Business type | Extra sources | What the report adds |
|---|---|---|
| D2C brands | Amazon and Flipkart listings, Instagram pages, review snippets | Price per unit, bestsellers, common complaints in reviews |
| SaaS startups | G2 and Capterra pages, pricing pages, Google Play reviews for mobile apps | Plans and pricing, features, what users dislike |
| Edtech | Course pages, app store reviews, YouTube channels | Course prices, languages offered, student complaints |
| Local service businesses | Google Maps listings and review counts, Justdial pages | Ratings, service areas, price ranges |
| Fintech | RBI licence information, app reviews, news coverage | Licence status, products offered, trust issues raised by users |
For fintech especially, I add a human check of regulatory details, because a mistake there matters more than a wrong feature list.
Students building a side project can use a lighter version too: skip paid sources, use only Exa AI and free-tier SerpAPI credits, and keep the Notion report to five competitors. It is a practical way to validate an idea before spending months building it.
Get AI competitor research for startups done for you
There are three ways to work with me on this:
- DIY: follow the setup above and build it yourself. If you get stuck on a node, send me a message.
- Done for you once: my team runs the research and delivers the Notion report and market map before your pitch.
- Workflow handover: my team builds the workflow in your n8n so you can rerun it whenever the market shifts.
Email me at contact@upcomingtools.com, or use the contact form with your website and the date of your next pitch. You can read who runs UpcomingTools, how I protect anything you share in the privacy policy, and the terms for paid projects in the refund policy.
